voices quoted
Quoted in this piece
Does SEO Still Work for AI Search? What Carries Over
SEO still works for AI search, but only the part that changes the page itself. A one-question test for which tactics carry over and which do not.

The short version
SEO still works for AI search, but only the part that changes the page itself. Ranking compares your page against others, while an AI answer reads one page it has already retrieved. Being crawlable, clear and specific carries over; link volume, keyword placement and rank tracking do not. Sort every tactic you pay for by that single test.
Key highlights
- 1 Google ranks pages by comparison; a model reads one retrieved page
- 2 A page can win the ranking and still fail the read
- 3 "SEO is the foundation" stops at retrieval, and retrieval is not selection
- 4 The test: does a tactic change the document, or only its standing?
- 5 Crawlability, speed and plain answers carry over; link volume does not
- 6 Sort your retainer by that test in about twenty minutes
- 7 Schema injected by a tag manager is invisible to the fetcher
- 8 Work on the overlap pays on both surfaces, so fund it first
- 9 SEO is not dead, and you do not need a separate AI team
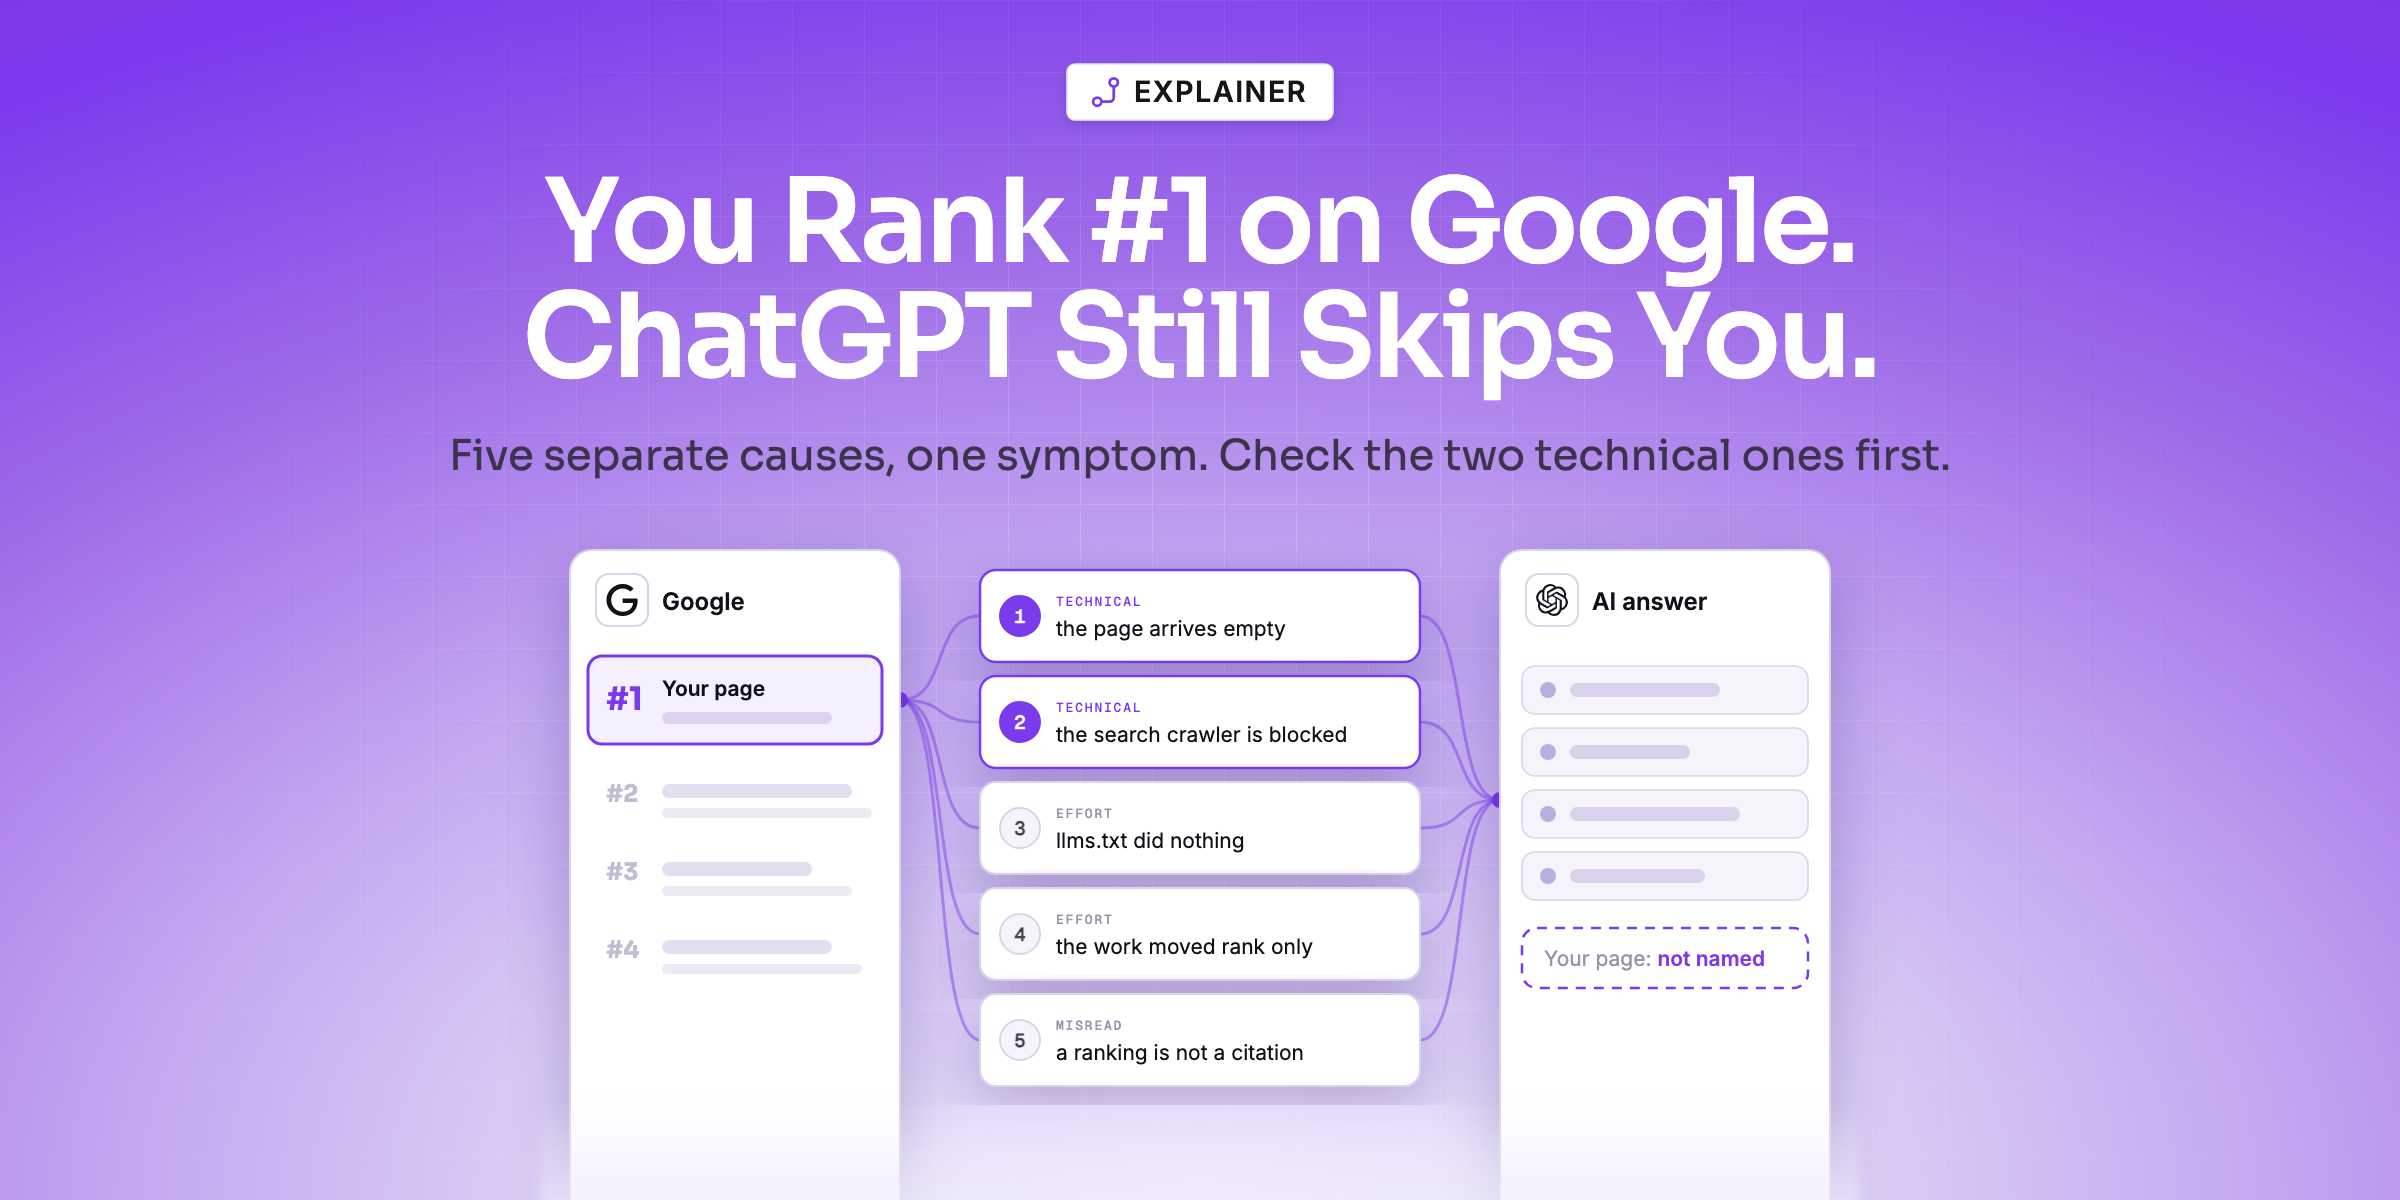
Somebody who paid for the number one ranking is asking why it did not carry. Your work is intact, the position is real, and the answer names four other companies.
The two available answers are both slogans. One says SEO is dead and you need a whole new discipline. The other says SEO is all you ever needed and the rest is vendor noise. Neither survives contact with what actually happens to a page.
The useful answer is narrower than both, and it comes with a test you can apply to every tactic you are currently paying for.
Google Ranks Pages. a Model Reads One.
The cleanest framing of it comes from someone who has to explain it to clients every week:
most clients come in assuming that if they rank well on Google they should automatically appear in AI answers. and when they do not they assume it is a content problem. more blogs, more backlinks, the usual. the reality is that Google ranks pages and ChatGPT reads them. those are two completely different things. when someone asks ChatGPT a question it does not check domain authority or count backlinks. it retrieves the page and reads what it can actually find in the document.
That is one practitioner's framing rather than a measurement, and it holds up because it describes two different operations rather than two different amounts of effort.
Ranking is a comparison across documents. Ten candidates exist, something scores them against each other, and you get an order. Everything that moves that comparison — links, authority, history, relative freshness — is doing work on the relationship between your page and everyone else's.
Citation is a read of one document. The page has already been retrieved. The question now is whether the specific sentence the model needs is in it, stated clearly, with evidence beside it. Nothing about your standing against other pages is available at that moment, because the comparison already happened and you are past it.
That is why a page can win the first operation and fail the second without anything being wrong with it.
It also explains why the failure is so hard to diagnose from the inside. Every instrument you own reports on the comparison — positions, impressions, share of voice against competitors. None of them describes the document. You can watch the first operation succeed in real time and have no visibility at all into the second one going wrong.
Both Camps are Half Right
The argument in the field is well described and both sides have a point:
For years, the formula was pretty straightforward: good content, strong backlinks, technical SEO, and topical authority. […] Some people say traditional SEO is still the foundation and that nothing has really changed. Others argue that AI visibility requires a different approach.
Here is what each camp gets right and where each one stops.
| The claim | What it gets right | Where it breaks |
|---|---|---|
| "SEO is still the foundation" | you must be crawlable, indexed and topically credible to be retrieved at all | it stops at retrieval, and retrieval is not selection |
| "AI visibility is a different discipline" | a second surface exists with different rules | it oversells the newness — most of the work is old work done properly |
Nothing you did stopped working on the surface it was built for. What changed is that a second surface appeared, where a different property of the page decides the outcome: whether the content is present and readable in what the fetcher actually received.
That is not more SEO and it is not a replacement for it. It is a different question about the same page.
The Dividing Line, Concretely
Here is the test, and it is one sentence: does this tactic change the document a fetcher reads, or only its standing against other documents?
| Carries over | Does not carry over |
|---|---|
| being crawlable and not blocked | link volume and link velocity |
| being fast enough to fetch reliably | keyword placement and density |
| covering a topic you genuinely know | position tracking and rank reporting |
| answering the question in plain sentences | anchor-text strategy |
| putting the evidence next to the claim | competitor backlink gap analysis |
| having the content in the raw response | domain authority as a target |
Look at the right-hand column. Not one of those things is worthless — they all still move rankings, and rankings still bring traffic. But every one of them operates on the comparison, and the comparison is over by the time a model is reading your page.
- The left column is mostly unglamorous. It is being present, being clear, and being specific — which is harder to sell than a link campaign and cheaper to do.
- The right column is where most retainers spend their hours, because it is measurable, reportable and familiar.
- The overlap is real. Good SEO gets you retrieved. It does not get you selected.
- Retrieval failures are cheap to fix and rarely looked at. Selection failures are the interesting ones, and almost nobody gets to them because the retrieval problem is still sitting there.

Run the Test on What You are Already Paying For
Take your current scope of work and sort it. It is a twenty-minute exercise and it usually reorders a quarter.
- List every activity on the retainer. Content production, technical fixes, link acquisition, reporting, whatever else.
- For each one, ask the single question. Does it change what is in the document, or only how the document compares?
- Check the "changes the document" items are actually landing. A rewrite that improves the page is worthless if the page arrives empty to the fetcher — that is a rendering problem, not a content one.
- Keep the comparison work you can still justify on its own terms. Rankings are a real channel with real revenue. Just stop expecting them to pay out twice.
A worked example of the sort, using three common line items:
- "Build 15 referring domains this quarter." Comparison work. It moves your standing and changes nothing in the document. Keep it if the traffic justifies it; do not count it as AI visibility work.
- "Rewrite the top 20 pages to answer the question in the first paragraph." Document work, and it pays on both surfaces. This is the line item to protect when the budget gets cut.
- "Add schema to product pages." Depends entirely on how it ships. Written into the server-rendered HTML, it is document work. Injected by a tag manager, it is neither — it is invisible to the fetcher and it looks fine in every test you would run.
That third case is the one that catches people. The same task, done two ways, lands in two different columns, and only one of the two is checkable without opening the raw response.
Two things usually fall out of that sort:
- Some of the best work on the list was already correct and nobody was framing it that way. Clear writing, specific answers and honest evidence were always the point.
- A rendering or access problem is hiding somewhere in the technical column, and it outranks everything else in priority because nothing downstream of it can work.
If you have not checked whether your pages arrive as readable documents, do that before any of the rest. A page whose content is assembled in the browser is invisible to a fetcher no matter how well it ranks, and that single check settles it.
Where the Two Surfaces Genuinely Overlap
It is easy to read the dividing line as two separate programmes of work. It is not. A large part of the carry-over column improves both surfaces at once, which makes it the cheapest budget you have.
| The work | What it does for ranking | What it does for citation |
|---|---|---|
| the answer stated plainly, early on the page | helps a snippet, helps dwell time | this is the sentence a model lifts |
| a specific claim with the evidence beside it | supports topical credibility | this is what a model checks before quoting |
| the content present in the server response | avoids rendering delays in indexing | decides whether you exist at all |
| genuine coverage of a subject you know | topical authority | you are retrievable for more of the fan-out |
| clean, fast, unblocked delivery | crawl efficiency | the fetch succeeds |
Every row pays twice. Nothing in the right-hand column of the earlier table does, which is the whole argument compressed into a budgeting decision.
- Fund the overlap first. It is the only spend that cannot be wasted on either surface.
- Then fund the comparison work on its own merits, sized against the traffic it genuinely produces rather than against a hope that it will carry over.
- Do not fund a new discipline on the strength of the gap. The gap is mostly explained by things you already know how to fix.
There is one more overlap worth knowing about, and it is the one people find surprising: the crawlers reading your site are not one thing, and telling them apart changes what your logs mean. Training crawlers, index crawlers and live fetchers behave differently, and a block or a delay affecting one of them does not affect the others.
What This Does Not Mean
It does not mean the work was wasted, and it does not mean there is a new discipline to buy.
- SEO is not dead. Search still sends traffic, rankings still convert, and the people declaring otherwise generally have something to sell you instead.
- You do not need a separate "AI team". The work that carries over is work an existing content and engineering team already knows how to do.
- Nothing here is a growth hack. There is no tag, file or schema type that substitutes for the page being clear and readable.
- The two surfaces are not in competition for your budget in the way vendors present it. Most of the carry-over column improves both at once.
The honest summary for the person who paid for the ranking: the ranking is real and it is doing its job. It was never evidence about a second surface that reads your page instead of comparing it, and nobody told them that because until recently nobody was asking.
If the next question is how to know whether you are being cited at all — that is a measurement problem rather than a cause, and it starts with what actually counts as a mention. Worth separating the two: this page is about why the ranking did not carry, not about how to check what did.
Conclusion
Your ranking is real and still doing its job, but it was never evidence about a surface that reads your page instead of comparing it. Fund the work that changes the document first, confirm that work actually reaches the fetcher, and keep the comparison work only where the traffic it brings justifies it on its own.
SEO and AI Search: Frequently Asked Questions
Does SEO still work for AI search?
Do backlinks matter for AI citations?
Is ranking 1 on Google enough to appear in AI answers?
Do I need a separate AI SEO strategy?
Is SEO dead?
What should I stop doing?
Find the exact growth leak in your business — in 2 minutes.
Paste your URL. Our AI agent crawls your site, diagnoses what's broken, and ships a step-by-step fix plan. Free, no signup.
Run free audit