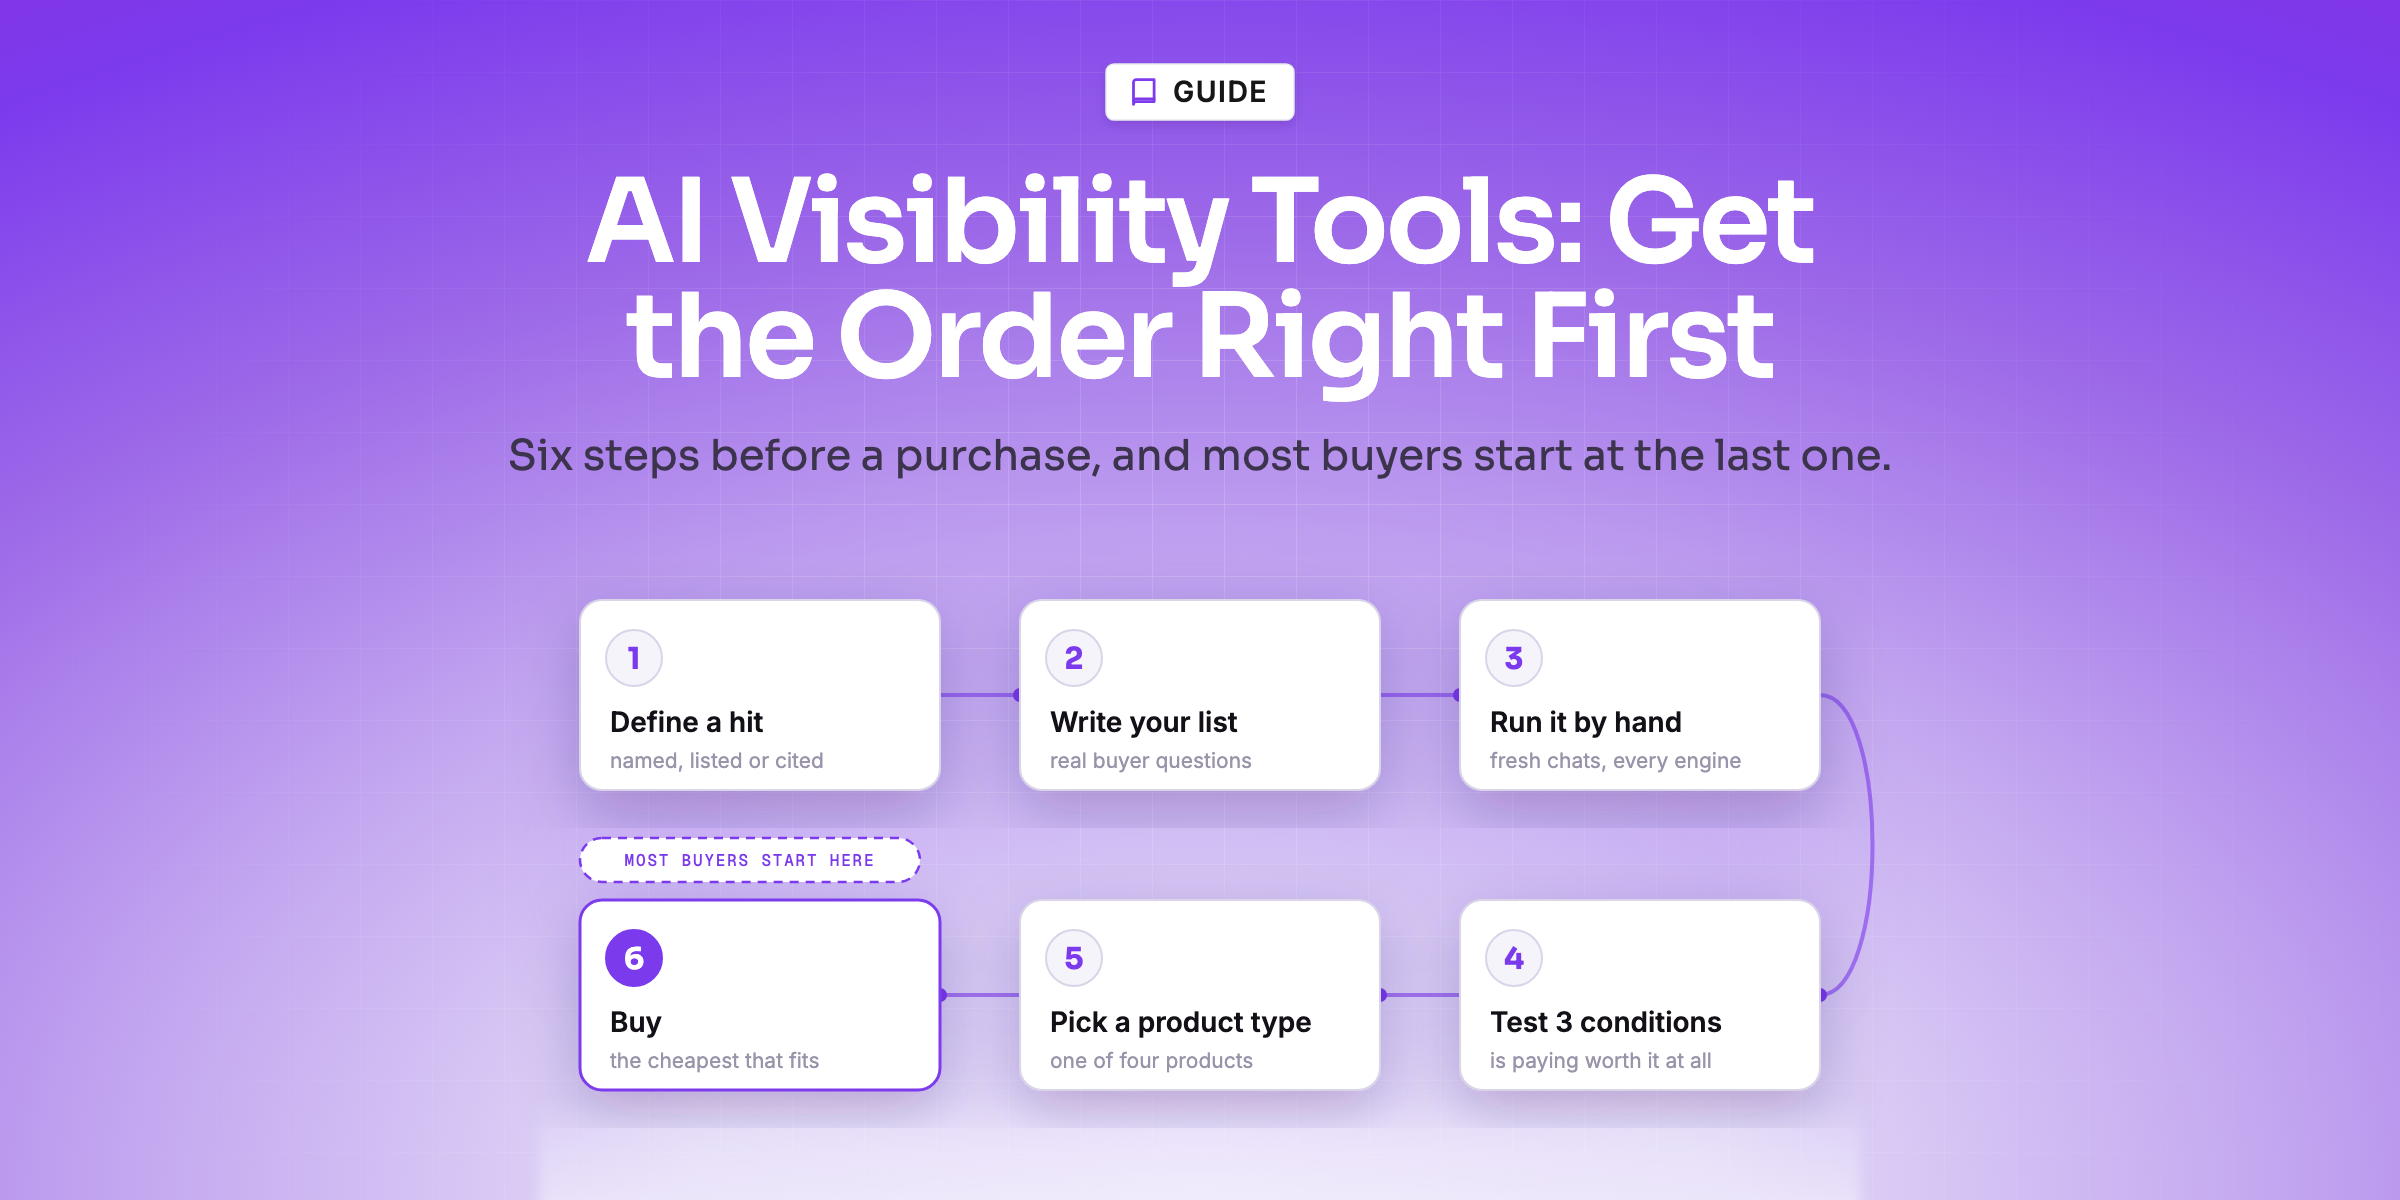
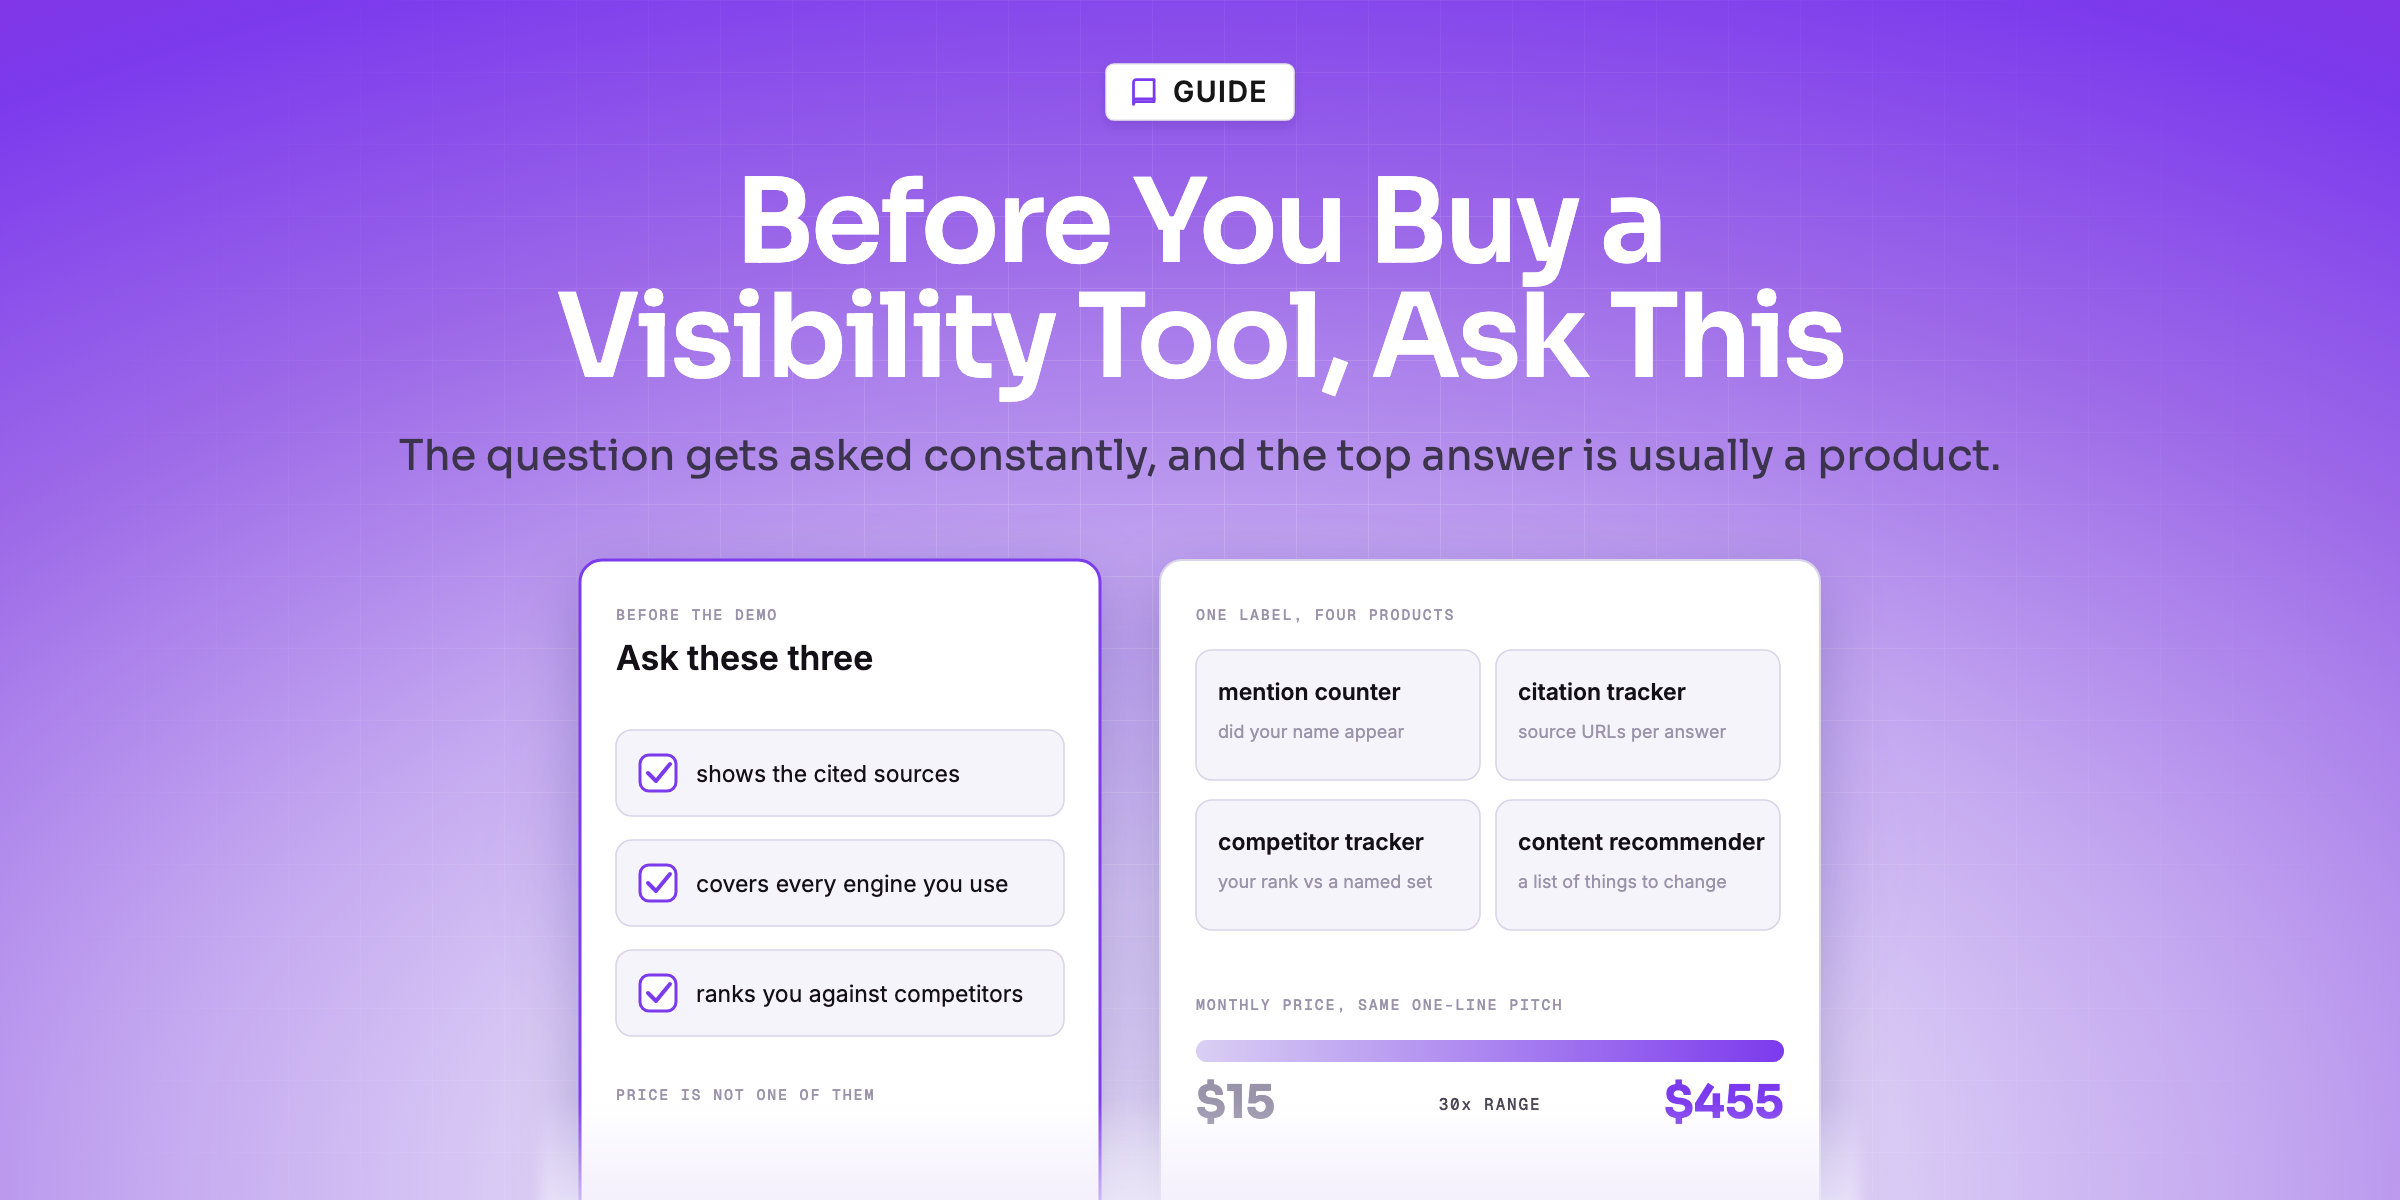
voices quoted
Quoted in this piece
How to Check Your AI Visibility by Hand, for Nothing
Check your AI visibility for free with a spreadsheet: unbranded buying questions, repeated runs per model, and a record of who got named instead of you.

The short version
You can check your AI visibility by hand in an afternoon, for nothing, and the number is better than a tool's because you chose the questions. Write 10 to 15 unbranded buying questions from real sales calls, run each 5 to 10 times per model in a fresh chat, and record who was named and which sources were cited. Avoid the four common mistakes that spoil the result. Start paying only when running the checks, not deciding them, becomes the cost.
Key highlights
- 1 Use unbranded buying questions, 5 to 10 runs each, in a fresh chat, per model
- 2 Record who else was named, not only whether you were
- 3 No vendor can supply your prompt set, because no vendor has your sales calls
- 4 Keyword tools are the wrong source; buyers write sentences, not keywords
- 5 A spreadsheet and a calendar entry cover a small list
- 6 By hand you read the answers and see who wins instead
- 7 Running from your own logged-in account is the most common error
- 8 Freeze the wording and decide the hit rule before you start
- 9 Buy when the running is the cost, not when the deciding is
Before you price a subscription, run the thing yourself once. It costs an afternoon, it produces the same unit the tools sell, and the number is better because you chose the questions.
That last part is not a consolation prize. Every product in this category reports a fraction, and somebody had to pick which questions go in the denominator. Do it by hand and that somebody is you.
Here is the whole method, published free by someone already doing it, plus where the questions should come from and the point at which paying starts to make sense.
The Method, in Full
Write 10 to 15 questions a buyer would actually ask, the kind with no brand name in them, like "best [category] for small teams" or "best [category] that works with HubSpot." Those are the ones that matter, since you already show up when someone types your name. Run each question 5 to 10 times per model, in a fresh or temporary chat so your history doesn't skew it. Put it all in a spreadsheet: question, model, run, which brands got named, which sources got cited.
That is the entire product, described in four sentences. Worth pulling apart, because each clause is doing work.
- Questions with no brand name in them. Asking "is Acme any good" tests whether the model knows you exist. Asking "best expense tool for a 20-person team" tests whether you get recommended, which is the thing that actually decides a purchase.
- Five to ten runs each. One run is an anecdote. The answers are composed fresh each time, so the variation between runs is part of the measurement rather than noise on top of it.
- A fresh or temporary chat. Your own account has been discussing your industry for months. That history skews the answer in your favour, which is the most common way a hand-run check flatters you.
- Per model. The engines behave differently enough that a blended figure hides whichever one moved.
- Which brands got named, and which sources got cited. Two columns, and the first is the one people forget. Who is recommended instead of you is more actionable than your own score.
| Column | What goes in it |
|---|---|
| question | the exact wording, unchanged between runs |
| model | and the mode — web search on or off |
| run | 1 to 10 |
| named you | yes / no |
| others named | every company in the answer |
| sources cited | the URLs, where the engine shows them |
| date | the day the run happened |
The date column looks like bookkeeping and is the one that makes the exercise repeatable. A rate without a date cannot be compared to next month's, and next month's comparison is the only benchmark that exists.
Ten questions across three models at five runs each is 150 answers. That is a long afternoon, or two shorter ones, and at the end of it you have something no dashboard has given anybody: a dated first-hand reading with a denominator you can defend.
Where Your Prompt Set Actually Comes From
This is the part that decides whether the whole exercise is worth anything, and one founder's answer to it is the sharpest in circulation:
[…] visibility using any of the huge list of existing AI visibility tools, because the methods of prompting such tools use are inaccurate. The only right way he found is: 1/ Record and transcribe all the discovery calls with potential customers. 2/ Enter the summary of the call as a prompt into AI chats and check whether your brand is mentioned as the best potential solution in such a situation. […] Yes, it's not scalable. You can't track your visibility every day and build a fancy dashboard this way, but you get more accurate data.
One account, not a study, and it argues against every product in the category — which is roughly why it is worth reading.
No vendor can supply your prompt set, because no vendor has your sales calls. That is the whole argument in a sentence. The questions a real buyer asked, in the words they used, before they had heard of you, are sitting in transcripts and support tickets you already own.
Where to mine them:
- Discovery and sales call recordings. The question behind the question, phrased the way a buyer phrases it.
- Support tickets and pre-sales email. Especially the ones from people who did not buy.
- The questions your team gets asked at events, which tend to be blunter than anything written down.
- Not keyword tools. Search volume describes what people type into Google. Nobody types a keyword into a chatbot; they write a sentence with constraints in it.

The Requirement the Market is Not Selling
There is a large gap between what small teams need and what the category ships.
I run content for a tiny startup with basically no budget, and every morning I manually copy the same prompts into ChatGPT and a few other tools to check whether our brand gets mentioned. I lose track of which prompts I ran, the answers change depending on wording, and comparing results week to week is messy. I just need something simple that runs a fixed prompt set on a schedule, saves the results, and flags when a mention appears or disappears. No huge dashboard and no $200 monthly plan.
Read what is being asked for: run a fixed list on a schedule, store it, flag changes. Three verbs. What gets sold is a dashboard, a competitive intelligence layer and a recommendations engine, priced accordingly.
If that is your requirement, you are closer than you think:
- You already own the hard part once the prompt set exists. Everything left is scheduling and storage.
- A spreadsheet plus a recurring calendar entry covers it for a small list, and the discipline is the same discipline a tool would impose.
- The flag is a column, not a feature. Last month's fraction beside this month's is the alert.
- A script is optional and not required. If somebody on the team can automate the running, do it. If not, the manual version is not a degraded version — it is the same measurement, slower.
One more thing that quote names and the category rarely does: it is not scalable, and that is fine. You cannot run discovery-call summaries every day or build a live dashboard from them. What you get instead is a small number of very accurate readings on the questions that actually preceded a purchase, which beats a large number of readings on questions nobody asked.
A workable compromise if both matter to you:
- A short, accurate set from real calls — five or six questions, run monthly, treated as the number you defend.
- A wider generic set — the "best X for Y" phrasings, run more often, treated as an early-warning signal rather than as the measurement.
- Never blend the two into one figure. They have different denominators and the average would describe neither.
What the Hand Method is Genuinely Better At
Two advantages that survive even after you can afford automation.
You read the answers. A dashboard hands you 40% and no sense of whether those four appearances were confident recommendations or a footnote in a list of eleven. Doing it by hand once teaches you what your category's answers actually look like, and you cannot recover that from a number afterwards.
You see who wins instead. The competitor names come out of the exercise automatically, and they are usually not the list you would have written. That is the single most useful output, and it arrives free.
There are real costs too, and pretending otherwise would be silly:
- It is genuinely tedious. 150 answers is a slog and it does not get more interesting.
- It is easy to do inconsistently. Different day, different mood, slightly different wording, and the comparison is void.
- It does not scale past a handful of questions. Twenty questions across four engines monthly is a job, not a task.
Common Ways a Hand-run Check Goes Wrong
The method is simple and there are four reliable ways to spoil it. All of them produce a number that looks fine.
- Running from your own logged-in account. The single most common error. Months of industry conversation in the history, and the model obligingly names the company you have been talking about.
- Rewording the question between runs. A word changed is a different question. Copy and paste rather than retyping, and keep the wording frozen across months.
- Counting a mention and a recommendation as the same event. Named in a list of five is not "recommended". Decide the rule before you start and write it at the top of the sheet.
- Stopping when the answer is good. If you run three, see yourself twice and stop, you have measured your own patience. Complete the set.
There is a fifth that is subtler. If two people split the runs, they will disagree about what counted, and the disagreement will only surface when the number is in front of a client. One person does all the counting, or the rule is written down well enough that two people land in the same place.
When to Start Paying
The rule is short: buy when the running is the cost, not when the deciding is.
Once the prompt set is frozen, the definition of a hit is written down, and the only work left is re-running the same thing on a schedule, a tool is buying back hours of mechanical labour. That is a good purchase.
Before that point, a subscription answers the wrong question. You would be paying somebody to decide what to measure, and their answer will be their prompt set — which makes your number theirs and stops it being comparable to anything else.
| Where you are | What to do |
|---|---|
| no prompt set, no hit definition | run it by hand. A tool cannot decide this for you |
| prompt set exists, running it monthly by hand | keep going until the hours hurt |
| hours hurt, list is stable, coverage matters | buy, and insist on uploading your own list |
| you want to know what to change | no tool answers this yet, at any price |
And before any of it, two free checks outrank everything: that a crawler can reach your pages and that you are not blocking it. A page that arrives empty cannot be cited however well you measure it, and what counts as a mention has to be settled before any number means anything.
Conclusion
Run the check yourself before you price a subscription. Build the question list from real buyer conversations, freeze it, run it in fresh chats across the engines that matter, and write down every competitor named. When the hours genuinely hurt and the list has stopped changing, buy a tool that will take your list unchanged.
Checking AI Visibility by Hand: Frequently Asked Questions
How do I check AI visibility for free?
How many prompts do I need to track?
Why use a fresh or incognito chat?
Where should my prompts come from?
Is a spreadsheet really as good as a paid tool?
When should I finally pay for a tool?
Find the exact growth leak in your business — in 2 minutes.
Paste your URL. Our AI agent crawls your site, diagnoses what's broken, and ships a step-by-step fix plan. Free, no signup.
Run free audit